
Grok Imagine 1.5 Prompt Guide: 8 Tips + Copy-Paste Templates
You type cinematic, 8K, masterpiece into a box and hit generate. Ten seconds later the clip looks like a stock wallpaper that learned to walk. The chorus still has no camera. A second music bed fights the song you already made. You did not fail at “being more creative.” You handed Grok Imagine 1.5 a mood board and asked it to direct a shot and score it.
People searching Grok Imagine 1.5 prompt already picked the model. What they want is a string they can paste: a short shot brief, official `<IMAGE_1>` tags for every uploaded still, a Sound: line written like a sound designer, then Music: none so the native audio pass does not invent a competing bed.
This is not a methodology lesson. Every tip below is a full block. The anti-example is the same intent written as empty adjectives. Paste the block, pick Grok Imagine 1.5 in the SunoMV audio-to-video generator, and export a shot that can sit on a chorus.
Table of Contents
- Why “cinematic, 8K” is not a Grok Imagine 1.5 prompt
- The official slots Grok Imagine actually uses
- 8 copy-paste tips
- 5 music-video templates
- Empty prompt vs a Grok Imagine 1.5 prompt
- FAQ
- Copy, pick Grok Imagine 1.5, export the MV
Why “cinematic, 8K” is not a Grok Imagine 1.5 prompt
Grok Imagine 1.5 is xAI’s video model. The lab’s own Video 1.5 announcement is blunt: give it a starting image (or a text shot), describe the motion, and choose resolution and duration. Sound effects, ambience, and speech land in the same pass as the picture. “Cinematic 8K” fills none of those slots.
On SunoMV the picker shows Grok Imagine 1.5. The row copy is fastest generation, more lifelike motion, and head and tail frame references. Official clips run 1 to 15 seconds. Resolution in the list is 480P, 720P, or 1080P. The model does generate from text alone. It does take a still as the opening frame. It does take up to seven reference stills, tagged in the prompt as `<IMAGE_1>` … `<IMAGE_7>`. It does not take a vocal file as Audio 1. That last fact is the whole reason this page is not a second launch recap. This page is only the pasteable prompt.
On this site, the same-cluster experiment is already measured. In May–July 2026, two Suno prompt pages sat at almost the same Search Console position: the copy-paste title (10 Tips + Copy-Paste Templates) pulled 3.79% CTR; the “7-Step Pro Method” title pulled 0.17% — a 22× gap on the same intent. The variable was the title shape, not “whether we optimized.” This page is the Grok Imagine 1.5 version of the winner shape.
Image: SunoMV Team · music-video still written as camera + subject + rain, not as “cinematic 8K”
Practical rule: If the first lines do not name the camera move, the subject action, and a
Sound:line — or tag`<IMAGE_1>`when you uploaded a still — you are decorating a shot the model already chose for you.
The official slots Grok Imagine actually uses
xAI’s public docs do not want MiniMax’s three labeled fields and they do not want FLUX 3’s HARD CUT schema. For Grok Imagine 1.5 they want a short shot brief: what moves, how the camera behaves, and what it sounds like. When stills are attached, they want those stills named in the prompt as `<IMAGE_1>`, `<IMAGE_2>`, in 1-based order.
| Slot | Fill this | Anti-example |
|---|---|---|
| Shot brief | Subject + action, then one camera move, then atmosphere | “cinematic music video, 8K, masterpiece” |
| Reference tags | `<IMAGE_1>` is the woman. `<IMAGE_2>` is the street. Up to seven stills | “use these references” |
| Head / tail | Open on <IMAGE_1>; end by resolving into <IMAGE_2>. | “morph between the photos” |
Sound: | Named objects: rain on leather, heel on wet asphalt, breath. Then Music: none | “make it sound epic” |
| Duration / ratio | Duration: 8 seconds. Aspect ratio: 16:9. (official window 1–15s) | “make it viral” |
| Continuity lock | Repeat wardrobe, hair, and one distinguishing mark in every shot | (nothing — the jacket recasts itself) |
The July 31 references update is the other half of the grammar: each still locks one thing — a face, a jacket, a street — without forcing that still to be the first frame. Keep the character and swap the scene, or keep the scene and swap the character. Text-to-video and image-to-video can run at native 1080p. Reference-to-video is capped at 720p. Write the resolution you will actually get.
This picker has no native negative-prompt field for Grok Imagine 1.5. Put “don’ts” as closing locks (Do not recast. Do not generate a new score.). Do not invent a second box.
This picker also has no audio-reference slot. MiniMax H3 on this site can take Audio 1. Grok Imagine 1.5 cannot. Native audio is generated with the picture. For a Suno MV, that means you name rain and heels, and you write Music: none so a second bed does not fight the track you already have.
A short look at what the model can hold together — one camera, physics, one pass of sound — is the official Grok channel cut of David Thompson’s Odyssey trailer:
Video: YouTube · Grok channel. SunoMV Grok Imagine 1.5 is one clip, 1–15 seconds, 480P / 720P / 1080P, with optional stills tagged as IMAGE_1.
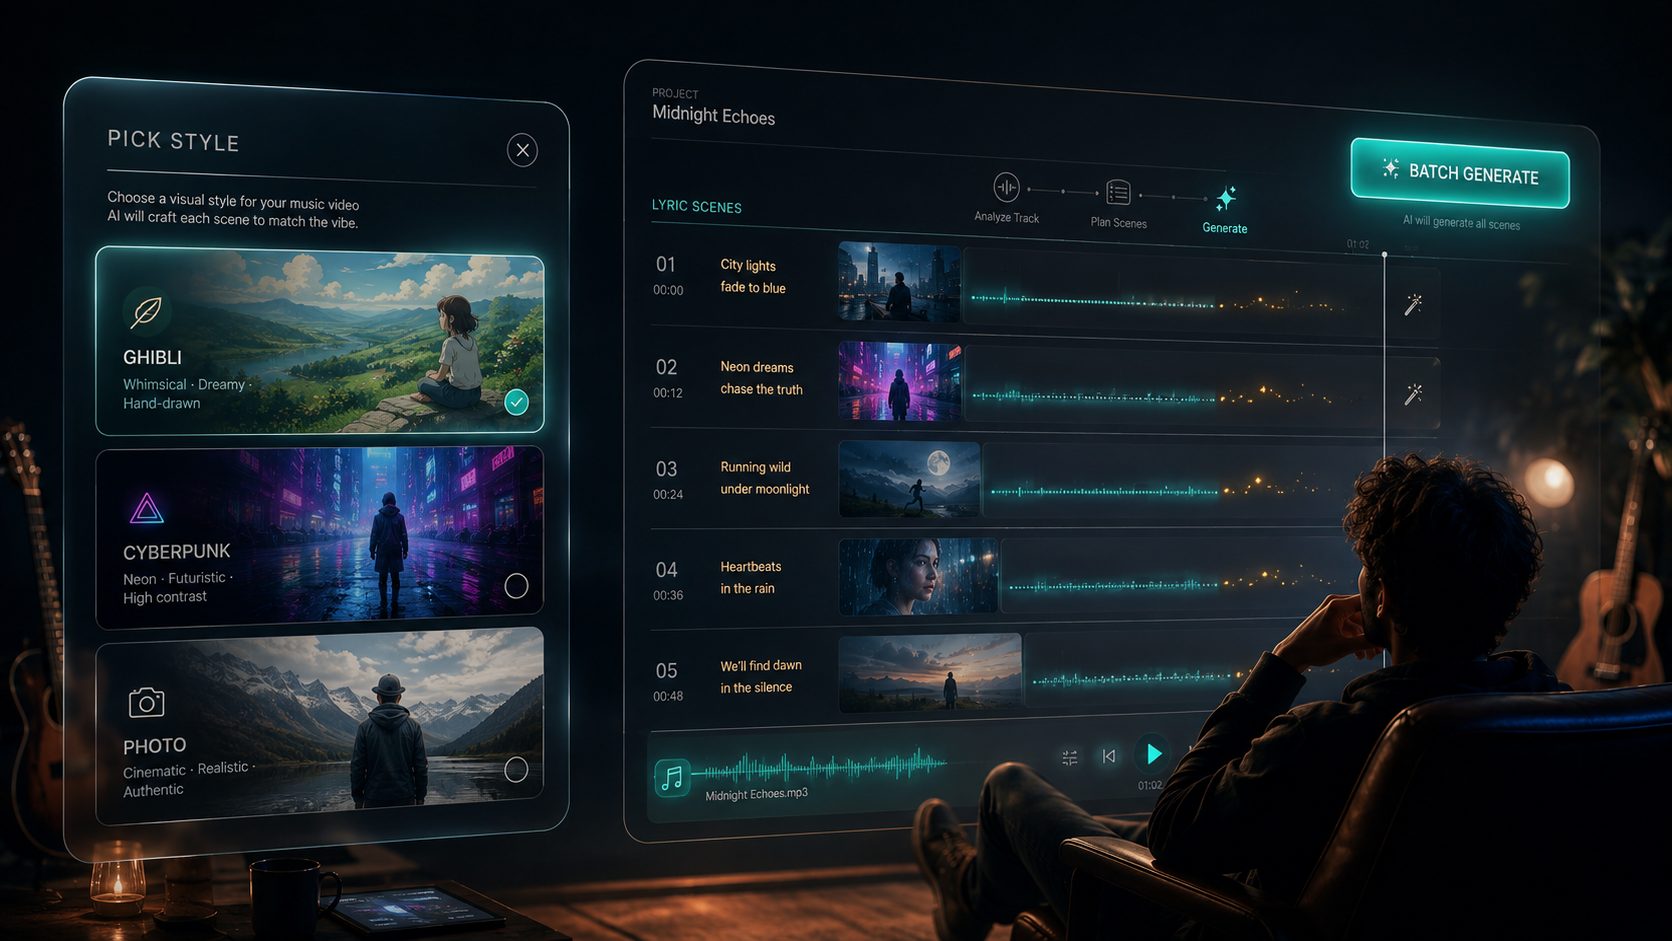
Image: SunoMV Team · Grok Imagine 1.5 is a row in the model list. The prompt still has to fill camera, subject, and sound.
Practical rule: Write a shot brief, not a caption. Tag every still. Put
Music: nonewhen the Suno track is already the score. Seven stills are a lock list, not a nine-image MiniMax face library.
8 copy-paste tips
Each tip is a full block. The anti-example is the same intent as empty adjectives. In SunoMV: pick Grok Imagine 1.5, paste the whole block into the shot description, generate, then cut the clip onto the lyric line.
1. Bind IMAGE_1 before you describe the shot
One-line rule: unlabeled files are wasted files. Official samples name the still inside the sentence — the model from <IMAGE_1> walks in — they do not say “use the attached photos.”
Duration: 8 seconds. Aspect ratio: 16:9.
<IMAGE_1> is the woman: late 20s, blunt black bob, oxblood leather jacket, white tank, silver hoops.
<IMAGE_2> is the Tokyo side street at night, wet asphalt, neon in puddles.
Medium close-up of the woman from <IMAGE_1> standing on the street in <IMAGE_2>. She mouths the chorus, left heel planted, jacket catching magenta neon. Slow push-in, 35mm, eye-level.
Sound: rain on leather, distant traffic, her breath on the inhales. Music: none.
Do not recast. Do not change hair.
Anti-example: Use the attached photos and make her sing. Cinematic music video.
How to use it in SunoMV: if you uploaded stills, this block goes first. A chorus still needs a face: pair `<IMAGE_1>` with at least one still so the mouth has someone to copy onto. If you uploaded nothing, skip the tags and start from text-to-video (tip 2). Tags are 1-based. Do not write MiniMax’s Image 1 here and do not write FLUX 3’s HARD CUT schema.
2. Start with a shot brief, not a mood board
One-line rule: xAI’s public examples read like a camera instruction — Slow cinematic push-in as embers drift across the battlefield — not a list of compliments.
Duration: 8 seconds. Aspect ratio: 16:9.
Medium close-up shot of a woman in an oxblood leather jacket standing in rain on a neon Tokyo side street at night. She mouths the chorus, left heel planted, jacket catching magenta neon. Slow push-in, 35mm, eye-level. Rain ticks on the leather. Do not recast. Do not change hair.
Sound: rain on leather, distant traffic. Music: none.
Anti-example: Epic cinematic banger, 8K, masterpiece, perfect lip sync.
How to use it in SunoMV: paste the whole paragraph as the shot description. If you uploaded a still, that still is the first frame — the brief still has to name the motion. See xAI’s image-to-video notes: the image holds the opening frame; the prompt drives what happens next.
3. Write the Sound: line like a sound designer
One-line rule: “city sounds” is a genre. “cars passing, skateboards on pavement, teenagers laughing” is a mix. Native audio lands on the action in the same pass. Unnamed sound becomes a second orchestra.
Duration: 8 seconds. Aspect ratio: 16:9.
Hip-height tracking left, 35mm, slow. She plants her left heel, weight forward, oxblood jacket swinging half a beat late. She mouths the line without smiling.
Sound: heel strike on wet asphalt, jacket leather, rain on a metal awning, one sharp inhale. No crowd cheer.
Music: none.
Do not generate a new vocal. Do not generate a new beat.
Anti-example: Perfect cinematic audio and an epic original soundtrack.
How to use it in SunoMV: keep Music: none on every chorus cut. You already have a Suno track. Named objects beat mood words. The same camera craft shows up in Runway’s camera-prompt notes — one framing term, one movement term.
4. Put duration and ratio in the first line
One-line rule: the official window is 1 to 15 seconds. Write the length you will actually get. A prompt that describes a minute of story will not get a minute.
Duration: 8 seconds. Aspect ratio: 16:9.
One continuous take, no cut inside the clip.
Start on her hands at the jacket zipper, end on her eyes as she looks up into the rain.
Camera: slow tilt up, 35mm, locked-off except the tilt.
Sound: zipper, rain, one inhale. Music: none.
Anti-example: A full music video that follows her all night across the city.
How to use it in SunoMV: one prompt = one generation, 1–15 seconds. For 9:16 Reels, change the ratio line only. Pick 1080P in the list when you want Full HD on text-to-video or image-to-video. Pick 720P when the shot is a reference generation (head/tail stills or extra identity stills) — that path is capped at 720p.
5. Name one subject the way a costume department would, then repeat it
One-line rule: “a girl” is a casting call. Wardrobe is a lock. Grok Imagine 1.5 on this site takes up to seven stills, not MiniMax H3’s nine. The same three-to-five anchors have to appear in the tags and after the camera line.
Subject: a woman in her late 20s, blunt black bob, silver hoop earrings,
oversized oxblood leather jacket over a white tank, chipped black nail polish.
Keep the same jacket and hair in every shot. Do not recast. Do not change hair.
Anti-example: A beautiful mysterious girl with good vibes.
How to use it in SunoMV: copy this subject block into every Grok Imagine 1.5 shot for the same song so the chorus and the verse do not recast her. If you need a still before the first video generation, pair it with musician image prompts — or generate that still on ChatImg with the same wardrobe line. Seven stills can cover face, profile, jacket, street, and two lights. They are a lock list, not a nine-image character bank. For true nine-still face-lock, pick Seedance or MiniMax H3 instead; this page is only Grok Imagine 1.5.
Image: SunoMV Team · seven stills lock identity; the prompt still has to repeat the jacket
6. Write action as physics, and write the camera as one move
One-line rule: “dancing beautifully” has no weight. “Heel strikes wet asphalt” does. “The wave crests” is vague; “the wave crests fully and pitches forward” is a direction. One camera move per clip. Stacking orbit + push-in + handheld usually warps.
Duration: 8 seconds. Aspect ratio: 16:9.
Camera: hip-height tracking left, 35mm, slow. Camera not orbiting.
Subject + action: she plants her left heel, weight forward, oxblood jacket swinging half a beat late. She mouths the line without smiling.
Sound: heel strike, jacket leather, rain, no applause. Music: none.
Anti-example: She dances beautifully with amazing energy and a low aerial handheld orbit push-in.
How to use it in SunoMV: if you stacked four camera words, delete two. Keep the heel. Keep Music: none. camera not moving is a legal lock when the subject should carry all the motion.
7. Head and tail stills still need a prompt — tag them, do not morph them
One-line rule: two stills hold identity. The prompt still has to name the path between them. On this picker, head and tail are reference stills, not MiniMax’s first/last-frame mode and not FLUX 3’s keyframe storyboard. Official mapping language: open on the first still, resolve into the second.
Duration: 8 seconds. Aspect ratio: 16:9.
Open on <IMAGE_1>; end by resolving into <IMAGE_2>.
<IMAGE_1> is the first frame: she stands outside the shop, both hands in her jacket pockets.
<IMAGE_2> is the last frame: she is one step closer, right palm on the glass, her reflection sharp in the window.
Take her from the ready stance in <IMAGE_1> through one step to <IMAGE_2>, flowing naturally, no extra cuts.
Camera: slow push-in, 35mm, eye-level. Rain ticks on the awning.
Keep face, bob, and oxblood jacket identical.
Sound: rain, one shoe on wet pavement. Music: none.
Anti-example: Image 1 and Image 2. Make a music video between them.
How to use it in SunoMV: upload the start still and the end still, then paste the path. Do not ask this mode for a three-shot montage — split those into separate generations. Reference generations on this row cap at 720p; do not pick 1080P and expect the extra stills to survive. The character-consistency method is the longer version of this lock on models that actually take nine stills.
8. For a music video, kill the generated score; this picker has no Audio 1
One-line rule: Grok Imagine 1.5 renders synchronized audio with the picture. A scene that implies rain will invent rain. A scene that implies “epic music” will invent a second bed. There is no Audio 1 slot to copy a vocal from.
Duration: 10 seconds. Aspect ratio: 16:9.
Medium close-up of the woman from <IMAGE_1>, oxblood jacket, blunt black bob, on the neon side street. She mouths the chorus. Slow push-in, 35mm. Copy the mouth rhythm of a sung chorus — stress on the downbeats, no smiling.
Sound:
  Ambience: rain against a metal awning, distant traffic
  Effects: heel on wet asphalt, leather jacket
  Speech: none
  Music: none
Do not generate a new vocal. Do not generate a new beat. Do not recast.
Anti-example: Perfect lip sync and an epic original soundtrack.
How to use it in SunoMV: drop the song (Suno link or your file) onto the timeline, pick Grok Imagine 1.5, keep one still as `<IMAGE_1>` so the face does not recast, and keep Music: none so the generated clip does not also invent a competing bed. Lip motion will be approximate — this is not MiniMax H3’s Copy phrase timing from Audio 1. If you need a vocal lock, use the MiniMax H3 prompt guide. If you need a picture-only lock with no native audio at all, see Kling O3.
Image: SunoMV Team · the usual failure is a second score, not a missing adjective
Practical rule: If you already have a Suno track,
Music: noneis the score lock. “Perfect lip sync” is not a slot on Grok Imagine 1.5.
5 music-video templates
Copy a block. Fill the brackets. Keep the shot brief and the `<IMAGE_*>` tags. Each template is one generation, 1–15 seconds.
Popular MV chorus (16:9, rain and neon)
Duration: 10 seconds. Aspect ratio: 16:9.
<IMAGE_1> is the woman: late 20s, blunt black bob, oxblood leather jacket over a white tank, silver hoops.
<IMAGE_2> is the rain-soaked Tokyo side street at night, magenta neon in the puddles.

Medium-wide of the woman from <IMAGE_1> walking toward camera on the street in <IMAGE_2>. She mouths the chorus. Camera: slow dolly in, 35mm, one move only.
Keep face, bob, and jacket identical.

Sound: rain, distant traffic, heel on wet asphalt. Music: none.
Do not recast. Do not generate a new score.
Lyric close-up (mouth + eyes, no recast)
Duration: 6 seconds. Aspect ratio: 16:9.
<IMAGE_1> is the woman with the blunt black bob and silver hoops.
Extreme close-up of the woman from <IMAGE_1>, 85mm, eyes and mouth only, tiny handheld drift. She sings one line, no smiling, catchlight from a pink tube light. Camera not pushing in. No cut. Keep the bob and hoops identical to <IMAGE_1>.
Sound: soft room tone only. Music: none.
Cinematic oner (one take, no invented cuts)
Duration: 12 seconds. Aspect ratio: 16:9.
Wide-to-medium tracking shot of a woman in an oxblood leather jacket walking a wet riverside promenade at blue hour. One continuous take. Slow dolly right, 35mm, eye-level. She looks once at the water, then forward. Hands in pockets. No cut. No time-lapse. Keep identity identical to <IMAGE_1>.
Sound: river, distant train, her footsteps. Music: none.
Vertical short (9:16, caption headroom)
Duration: 8 seconds. Aspect ratio: 9:16.
Medium close-up of the woman from <IMAGE_1> with the blunt black bob, subject in the center third, headroom for captions. Neon stairwell, one pink tube light. She looks up, blinks once, then mouths the hook. Camera locked off. Keep her identical to <IMAGE_1>.
Sound: hum of the tube light. Music: none.
Head-and-tail transition (two stills, not a face library)
Duration: 8 seconds. Aspect ratio: 16:9.
Open on <IMAGE_1>; end by resolving into <IMAGE_2>.
<IMAGE_1> is the chorus still: she stands at the shop window, both hands in the oxblood jacket.
<IMAGE_2> is the last frame: she is one step closer, right palm on the glass, magenta neon in the reflection.
Take her from <IMAGE_1> to <IMAGE_2> in one step, flowing naturally, no extra cuts.
Camera: slow push-in, 35mm, eye-level. Rain ticks on the awning.
Keep face, bob, and jacket identical.
Sound: rain, one shoe on wet pavement. Music: none.
You do not need seven stills every time. Two consistent stills already beat one pretty headshot used as a “reference library.” The AI music video creation guide is the workflow for stringing those shots.
Practical rule: A template is finished when duration, ratio, wardrobe, one camera move, tagged stills, and
Music: noneare all on the page — never “epic music.”
Empty prompt vs a Grok Imagine 1.5 prompt
Same song, same 10 seconds, two inputs. Only one of them is a Grok Imagine 1.5 prompt.
| Empty | Copy-paste | |
|---|---|---|
| First lines | “cinematic, 8K” | shot brief: camera + subject + action |
| Stills | “use these” | `<IMAGE_1>` / `<IMAGE_2>`, 1-based |
| Subject | “a girl” | wardrobe + hair + one distinguishing mark, repeated |
| Action | “dancing” | heel, weight, contact with the ground |
| Time | (none) | Duration: 10 seconds summing to ≤15s |
| Audio | “perfect lip sync + epic music” | named rain/heels; Music: none |
| Continuity | (hope) | seven stills max; repeat the jacket |
| Who it’s for | a still that pretends to be a video | a chorus cut you can actually edit |
If you already have a Suno track, do not ask Grok Imagine 1.5 to write another one. Point it at the picture, kill the generated score, keep the song. For a MiniMax-shaped vocal lock (Audio 1), see the MiniMax H3 prompt guide. For FLUX 3’s one-liner and HARD CUT schema, see the FLUX 3 prompt guide. For a Kling-shaped picture-only lock, see the Kling O3 prompt guide. For Seedance-style second-level timestamps, see the Seedance 2.5 prompt guide. Different slots, same “copy the block” job.
This page is not a vs review. The sister-site still-image comparison — Grok Imagine Image 2.0 against GPT Image — lives on ChatImg and is a still workflow. Do not paste that article’s edit prompt into this box and expect a chorus cut.
A sister-site note if you also need a transcript of the finished MV: BibiGPT’s YouTube transcript generator is the paste-a-link path for that, not this page.
Practical rule: If you cannot point to a tagged still (or a head-and-tail pair), plus
Music: none, you do not have a Grok Imagine 1.5 music-video prompt. You have a vibe.
FAQ
Do I write “Grok Imagine 1.5” inside the prompt?
No. The model name does not belong in the prompt text. People search Grok Imagine 1.5 prompt; SunoMV’s picker lists Grok Imagine 1.5. Pick in the list, not in the sentence.
Why did my clip stay at 15 seconds when I described a whole night?
Write the duration as a field. xAI’s public window is 1–15 seconds. A prompt that describes a minute of story will not get a minute. See the audio-to-video generator.
Head and tail: do I still write a prompt?
Yes. The stills hold identity. The prompt still has to name the camera and the step between them, and it must not ask for extra cuts. Use Open on <IMAGE_1>; end by resolving into <IMAGE_2>. See tip 7. That is a two-still path, not MiniMax’s first/last-frame box and not a nine-image character library.
Why is there a second music bed under my Suno track?
You left audio empty or wrote “epic score.” Fill Music: none, and name the rain. Grok Imagine 1.5 generates sound with the picture; it cannot take Audio 1. That is the opposite of MiniMax H3, which can.
Can I upload nine face stills to lock the singer?
Not nine. This row takes up to seven reference stills. Face-lock with up to nine images is Seedance / MiniMax H3 on this site. Repeat the wardrobe line, stay inside seven, or switch model. See the character-consistency method.
Why did 1080P fail when I added extra stills?
Text-to-video and image-to-video on Grok Imagine 1.5 can run at native 1080p. Reference generations — extra identity stills, or a head-and-tail pair — are capped at 720p. Pick 720P for those shots. Specs independent of this site live in xAI’s Video 1.5 references note.
Should I write negative prompts?
Not in a separate box — Grok Imagine 1.5 here has no native negative field. Put exclusions in the description: Do not recast. Do not generate a new score.
Can one prompt be the whole music video?
No. One prompt is one generation: 1–15 seconds. String the shots. This page is only the pasteable Grok Imagine 1.5 prompt. The AI music video creation guide covers the string.
Is this the same as Grok Imagine Image 2.0?
No. Image 2.0 is a still-image line (text rendering, region edit). Grok Imagine 1.5 here is the video line: time, camera, and synchronized audio. Do not paste a still-edit prompt into this box.
Copy, pick Grok Imagine 1.5, export the MV
A Grok Imagine 1.5 prompt is finished when you can paste it, not when you can explain it.
- Copy one template above. Fill the brackets. Keep the shot brief. Tag
`<IMAGE_1>`. Repeat wardrobe. WriteMusic: none. - Open the SunoMV audio-to-video generator. Drop in the song (Suno link or your own file).
- In the model list, pick Grok Imagine 1.5. Set 1–15 seconds. Use 1080P for text or a single first frame; use 720P when extra stills or a head-and-tail pair are in the shot.
- Paste the whole prompt into that shot. If you uploaded stills, say what
`<IMAGE_1>`/`<IMAGE_2>`are for — do not treat them as an unlabeled pile. - Export the clip onto the lyric line. Repeat. The MV is the string of shots, not one heroic paragraph.
Every model you can click is a prompt guide that has not been written yet. The people who get usable Grok Imagine 1.5 footage are not the ones with a better adjective list. They are the ones who already have a pasteable prompt before they touch generate.
SunoMV Team
Popular guides